Translating Raw Production Traces Into a Prioritized Agent Improvement Backlog
Systematic tracing turns agent failures into ranked, evidence-backed fixes instead of guesswork.
A production trace-driven harness engineering workflow turns live failures into verified improvements by detecting errors, attributing them to a specific harness layer, clustering them by recurrence and impact, and ranking fixes by evidence weight. Historical replay then tests each proposed change before it ships. The purpose is to replace guesses about prompts with an inspectable backlog grounded in how the agent actually failed.
Why raw traces alone cannot drive agent improvement
The logs exist, the run failed, and the cause remains opaque. A final answer may be wrong even though the tool calls appear to have completed successfully. A run may also have errors that the agent fixed before it finished. A large, heterogeneous log stream does not distinguish these cases on its own, so its volume cannot substitute for a method that separates symptoms from causes.
AgentChaosBench establishes why final task outcomes are insufficient for diagnosis. Agent reliability depends on the whole execution, including tool calls, model calls, guardrail decisions, and inter-agent messages. Faults can propagate across those boundaries before becoming visible. A remote tool’s plausible but corrupted response can surface later as an incorrect answer, while a model call that exceeds its context budget can contribute to a stalled workflow.
The difficulty is structural. ReAct-style agents interleave reasoning with tool calls, leaving behavioral structure implicit in the trace. Automata from Agent Traces finds that this behavioral topology appears shaped more by the deployment harness than by the underlying model. That points work on improvements toward the instructions, tools, memory, and runtime controls around the model. A failed outcome is therefore the entry point for investigation, with further evidence needed to justify a prompt change.
What a complete instrumentation layer must expose before diagnosis is possible
Diagnosis needs agent identity, guardrail decisions, and agent-to-agent interactions as well as model requests and tool responses. Each step also needs timing and status. Without those fields, a slow tool invocation and a delayed handoff may look much the same at the end of a run, with too little evidence to tell which caused it. Capture determines what downstream analysis can establish.
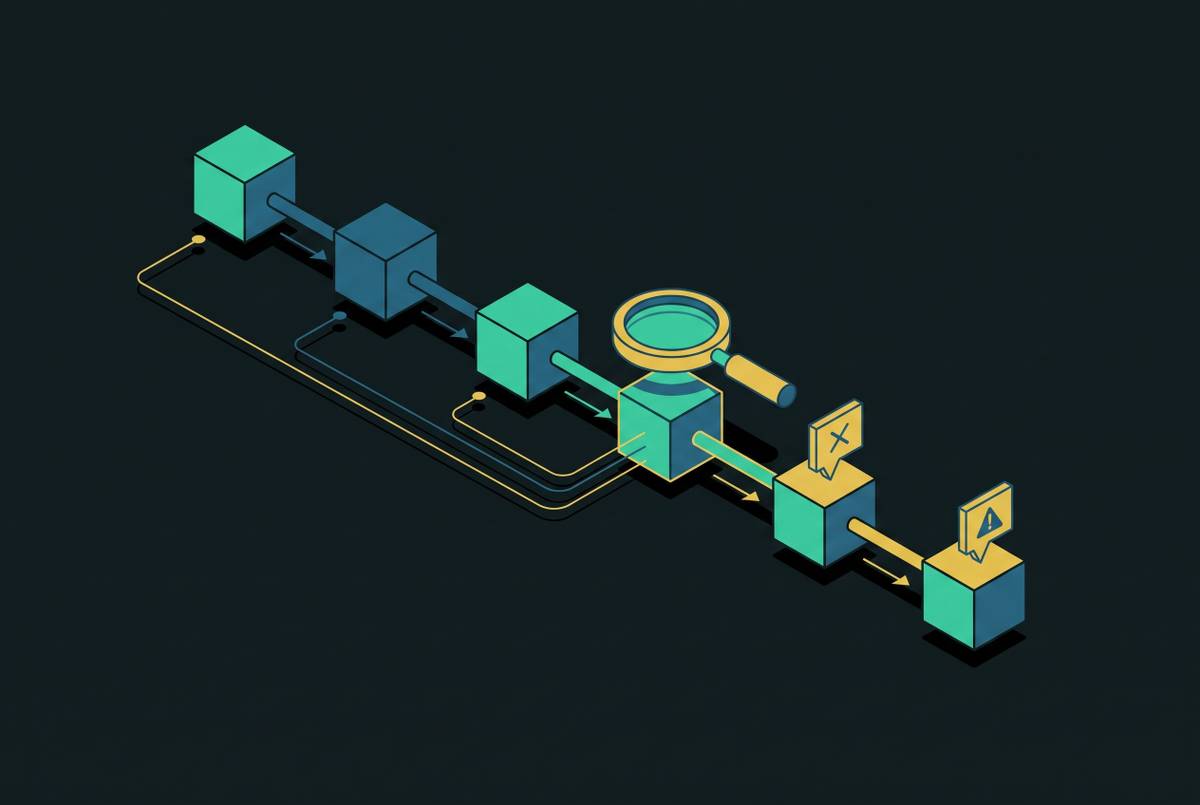
The span hierarchy provides the practical unit of analysis. An invoke_workflow span represents the full workflow, while an invoke_agent span represents an individual agent’s processing. Beneath these, chat or LLM spans describe single model calls, execute_tool spans describe external API invocations, and retrieval and embeddings spans expose their respective operations. The associated fields include input and output tokens, latency, model name, finish reason, and error type where applicable. OpenTelemetry GenAI semantic conventions are converging as the dominant instrumentation standard, with agent and tool decorators available, but remain in Development status.
The hierarchy connects each operation to its execution context. Engineers can follow input, plan, retrieval, tool arguments, tool output, model rewrite, and final answer, scoring spans to locate where behavior diverged. AgentChaosBench finds that reference-dependent faults, such as a bypassed guardrail, are near-unsolvable from a single trace alone. Storing aligned no-fault reference executions with failed runs preserves the comparison needed to diagnose those cases.
The failure taxonomy that gives clusters their meaning
A shared taxonomy makes recurrence legible across different tasks. The MAST taxonomy distinguishes specification and system design failures from inter-agent misalignment. The first category includes task misinterpretation, ambiguous role definitions, poor decomposition, duplicate agent roles, and missing termination conditions. The second includes communication breakdowns, information withholding, ignored agent inputs, and reasoning-action mismatches.
Tool invocation errors form another working category. AgentChaosBench characterizes faults at tool, model, guardrail, and inter-agent boundaries, where call-level failures include incorrect argument values, names, or types, repeated API calls, hallucinated function names, and invalid output formatting. Schema drift is a quieter variant. The model may follow a previously learned tool contract while the system enforces a renamed field, new required property, changed enum, or stricter validator, producing failures without an explicit error signal.
Workflow loops describe retries, tool-call iterations, or multi-agent conversations without bounds. Parser errors and validator failures can redirect execution into these loops, whose dominant impacts include API cost exhaustion and model denial of service. Context blow-out and drift develop in a different way. Accumulated transcripts exhaust the context window, truncation disconnects plausible output from earlier content, and prompt chains compound small errors across steps.
These categories describe observable failures, but they do not establish causality. TRAJDEBUG distinguishes local errors from critical errors by their resolution status and terminal impact. A local error may be repaired or prove inconsequential. The critical error can be somewhere other than the first error or the one closest to the failed outcome, so attribution takes more work than labeling.
Attributing each failure to its responsible harness layer
Attribution turns a failure label into a claim about responsibility. The relevant layer may be the prompt, tool, workflow, memory, model, or inter-agent handoff, and that location determines the kind of change proposed. Most actionable production failures sit in the surrounding harness, including instructions, verification rules, permission policies, and runtime mechanisms. A diagnosis that ends at “the agent reasoned incorrectly” leaves those possible causes unresolved.
A tool schema error and a workflow loop illustrate the distinction. If the trace shows argument names that do not match the enforced tool contract, attribution can point to the tool layer and identify the conflicting schema evidence. If calls repeat after validator failures and there is no termination condition, workflow control is the likely responsible layer. The reviewable output must connect the symptom to the responsible layer.
TRAJDEBUG separates error trigger detection, error state classification, and critical attribution, using multi-granularity history compression to handle long executions. ErrorProbe starts with taxonomy-based anomaly detection, traces backward from the failure symptom to prune irrelevant context, and validates hypotheses through tool-grounded execution. Its Strategist, Investigator, and Arbiter team updates verified episodic memory only when executable evidence confirms an error pattern.
Automation still requires a firm review boundary. In AgentChaosBench’s 2026 evaluation, even frontier models reach only roughly 25% top-1 fault-type diagnosis accuracy when they use structured trace views. Engineers therefore need an inspectable attribution claim and its evidence before acting. The automata study adds a complementary basis for that review by collapsing traces into a finite-state machine whose failure-associated states ground diagnosis in cross-run behavior.
Clustering attributed failures by recurrence and impact before sequencing fixes
Attributed failures become useful backlog candidates when they recur across runs with the same failure type and responsible layer. Incorrect answers caused by corrupted tool output should be checked before they are put in the same cluster as incorrect answers caused by context truncation. The grouping must preserve the distinction that determines which artifact needs to change.
Recurrence is the first dimension of cluster strength. The automata study finds stable behavioral topology across training splits, allowing per-state features to accumulate evidence from many executions. When a failure repeats in a high-traffic state, a shared pattern is visible across the incidents. Its monitor can also rank failing runs above passing ones from partial traces and trigger early stopping before completion.
Impact is the second dimension, measured through the consequences visible in execution. Workflow loops that exhaust API budget outrank an isolated hallucination with no downstream effect. Schema drift on a tool path used often should rank above the same drift on a tool that is rarely called. Recurrence establishes the pattern’s reach, while impact establishes the damage associated with each occurrence.
Confirmed patterns can also span task domains. ErrorProbe’s verified episodic memory accumulates error patterns without retraining, allowing a confirmed pattern in one task type to support recognition in another. Skills libraries require a distinct cluster category because unbounded skill accumulation can produce retrieval disorder. Its forms include channel fracture when retrieval cross-contamination occurs, knowledge fragmentation when composition is incoherent, and behavior routing deficiency when the wrong skill is selected.
Sequencing the backlog by evidence weight
Evidence weight sets which cluster engineers work on next. The strongest candidate has confirmed traces that have been replicated and point to the same bounded layer, with high impact each time the failure occurs. Cluster size counts each production run once, so repeated steps inside one looping run count as one incident. Layer specificity then separates a concrete finding about a tool schema from a diffuse claim about general reasoning.
A backlog item makes that evidence inspectable. It contains the failure cluster name, responsible harness layer, artifact type, cluster size, estimated impact, and proposed fix. For an illustrative schema-drift cluster, the item would identify the tool layer, name the affected tool schema as the artifact, and describe the contract mismatch found in the traces. Its proposed change would target that mismatch. The size and impact fields would use the recorded run count and the effects seen in those runs, with only as much precision as that evidence supports.
Fix tractability influences sequencing once the evidence is clear. Changes to a prompt or tool schema usually ship faster than changes to the workflow structure, while changes to memory architecture carry more risk. A well-bounded fix can therefore be more actionable than a broad intervention with uncertain responsibility. Stronger evidence for a workflow defect should still rank above a prompt edit that is easy to make.
Regression risk also affects the next step. A proposed fix on a high-traffic harness path ranks higher for immediate validation than one affecting an edge-case path, because more execution depends on it. This is a reason to test urgently. The ordered backlog thus distinguishes evidence for the defect from confidence in the proposed remedy, which remains unproven until replay.
Validating proposed fixes against historical traces before shipping
Replay is the gate between a proposed fix and a shipped improvement. A change may resolve the named failure while introducing a regression in a related path. The engineering sequence is to find the problem in production, reproduce it locally, add it to evals, fix it, verify that the eval passes, and ship. Historical traces make reproduction tractable without calling external systems again.
Replay mode replaces live tool calls with their recorded responses. With all tool calls captured, engineers can reproduce a bug deterministically, score it against real rubrics, and retain it as a regression test in CI. Chronicle’s cut-point replay formalism executes new code at a recorded crossing and records the outcome as a regression test. This differs from attribution, which characterizes why the past execution failed.
Validation continues across the release cycle. Before shipping, CI gates replay a curated golden set against the proposed harness change. During iteration, replay on every candidate prompt or tool change shortens the path to a confidence signal. After shipping, production monitoring detects drift, tool breakage, and unsafe behavior against the same trace corpus.
Scheduled replay makes drift a backlog input. Running the golden set daily or on every deploy, with expected outputs or rubric scores, allows a sustained score drop to reopen the relevant cluster. Schema drift needs its own CI gate that records tool schemas, compares them on each run, and fails when a change would break the contract, before that violation reaches production. The resulting shipped change is evidence-backed, inspectable, and reversible. Its new production traces then supply the next round of failures, attributions, and ranked work.
Sources
- When Agentic Executions Fail: Detecting and Localizing Runtime Faults from Telemetry
- TRAJDEBUG: Tracing Error Lifecycle to Identify Critical Failures in Long-Horizon Agent Trajectories
- Automata from Agent Traces: Failure and Next-Step Prediction
- Towards Self-Improving Error Diagnosis in Multi-Agent Systems
- When Agentic Executions Fail: Detecting and Localizing Runtime Faults from Telemetry