Prioritizing Agent Fix Backlog by Production Failure Impact
Ranking agent fixes by production impact and failure type prevents costly misalignment delays.
Prioritizing Agent Fix Backlog by Production Failure Impact.
Agent fix backlogs without a priority signal
Agent failures in production are not the rare, isolated glitches that traditional bug triage assumes. The MAST study found failure rates ranging from 41 to 87 percent across more than 1,600 annotated traces spanning seven popular multi-agent frameworks. At that scale, a fix backlog stops looking like a queue and starts looking like a flood, and no engineering team can treat every item as equally urgent without some way to rank them.
The trouble is that agent failures are structurally heterogeneous. Tool-call errors, ambiguous prompts, infinite workflow loops, and quiet behavioral drift do not share a common signature, so lumping them into one undifferentiated list produces an ordering that's essentially arbitrary. Worse, the step where a failure becomes visible is often not the step that caused it, according to the TRAJDEBUG research out of Tsinghua University and Tencent Hunyuan. A team fixing the symptom instead of the origin ships a patch that looks complete and changes nothing.
Old triage heuristics, severity labels, stack-ranking by whoever complained loudest, don't transfer cleanly here either. Many agent failures never raise an exception at all: the agent finishes its task and returns a confident, wrong answer, with nothing in the logs to flag it. Downstream damage from an early miscalculation is invisible unless someone has trace-level evidence connecting the origin to what came after. The cost of guessing wrong is not abstract. A loop incident in November 2025 burned $47,000 over eleven days because no planning-layer evaluation existed to catch the cycle before it ran up compute charges futureagi.com.
A defensible ordering needs three inputs, applied consistently to every item sitting in the queue: how often a failure actually recurs in production, how far its damage spreads downstream, and whether it keeps appearing in the same architectural layer. Frequency alone flatters loud, visible failures and buries the silent ones. Blast radius alone ignores how often something happens. Layer recurrence tells an engineering team whether they're looking at a one-off mistake or a structural defect worth fixing once and for all. Put together, the three dimensions turn a pile of unranked complaints into a queue someone can actually defend to a director asking why this ticket got fixed before that one.
What makes agent failures structurally hard to rank
Before any of that scoring can happen, two distinct populations of failure need separating. One category behaves the way software bugs traditionally do: visible, terminal, and loud enough that a monitor catches it in real time. The other kept every detector green and only became visible hours or months after the fact, once someone noticed the downstream damage. A 2026 longitudinal taxonomy distinguishes production incidents from the other population explicitly, treating the two as complementary rather than interchangeable, and that distinction matters enormously for prioritization, because a queue built entirely from incident reports will never reveal the second kind at all.
Within a single failed trace, the field has also converged on a useful idea: the decisive error. The Who&When benchmark, from Zhang et al. in 2025, defines it as the earliest mistake whose correction could have reversed the entire outcome. Chasing that one error is far more actionable than trying to catalogue every mistake in a trajectory, most of which turn out to be noise once the trace is fully unpacked. TRAJDEBUG's research reinforces the finding that the critical error is not necessarily the first local mistake, and it isn't necessarily the one sitting closest to the final failure either. Failed trajectories tend to contain several coexisting errors, some quietly repaired later in the run, some harmless, and only a few that actually cause the outcome everyone's upset about.
This is where standard observability tooling runs into a wall. Origin-step accuracy, the ability to say where the failure actually started, dropped to at most 0.5 percent under the same conditions TelemetrySuffBench. Standard tracing tells a team a failure happened. It almost never tells them where.
The same research found that stripping the decision content out of trace records, the reasoning that led an agent to take a given action, causes origin-step accuracy to fall to zero across every model tested. Decision-to-provenance links are the one piece of data without which no prioritization framework can honestly call itself trace-grounded. A backlog item ranked on error count or alert volume alone is ranked on the wrong signal entirely, because that signal describes symptoms rather than causes.
The MAST failure taxonomy as a shared vocabulary for backlog categories
Before scoring anything, a team needs a common language for what it's even looking at, and MAST supplies the closest thing the field has to one MAST Study. Cemri and colleagues built the taxonomy from more than 1,600 annotated execution traces across seven frameworks, with six expert annotators reaching a Cohen's Kappa of 0.88, making it the most widely cited, empirically grounded failure taxonomy currently in circulation MAST Study MAST Taxonomy.
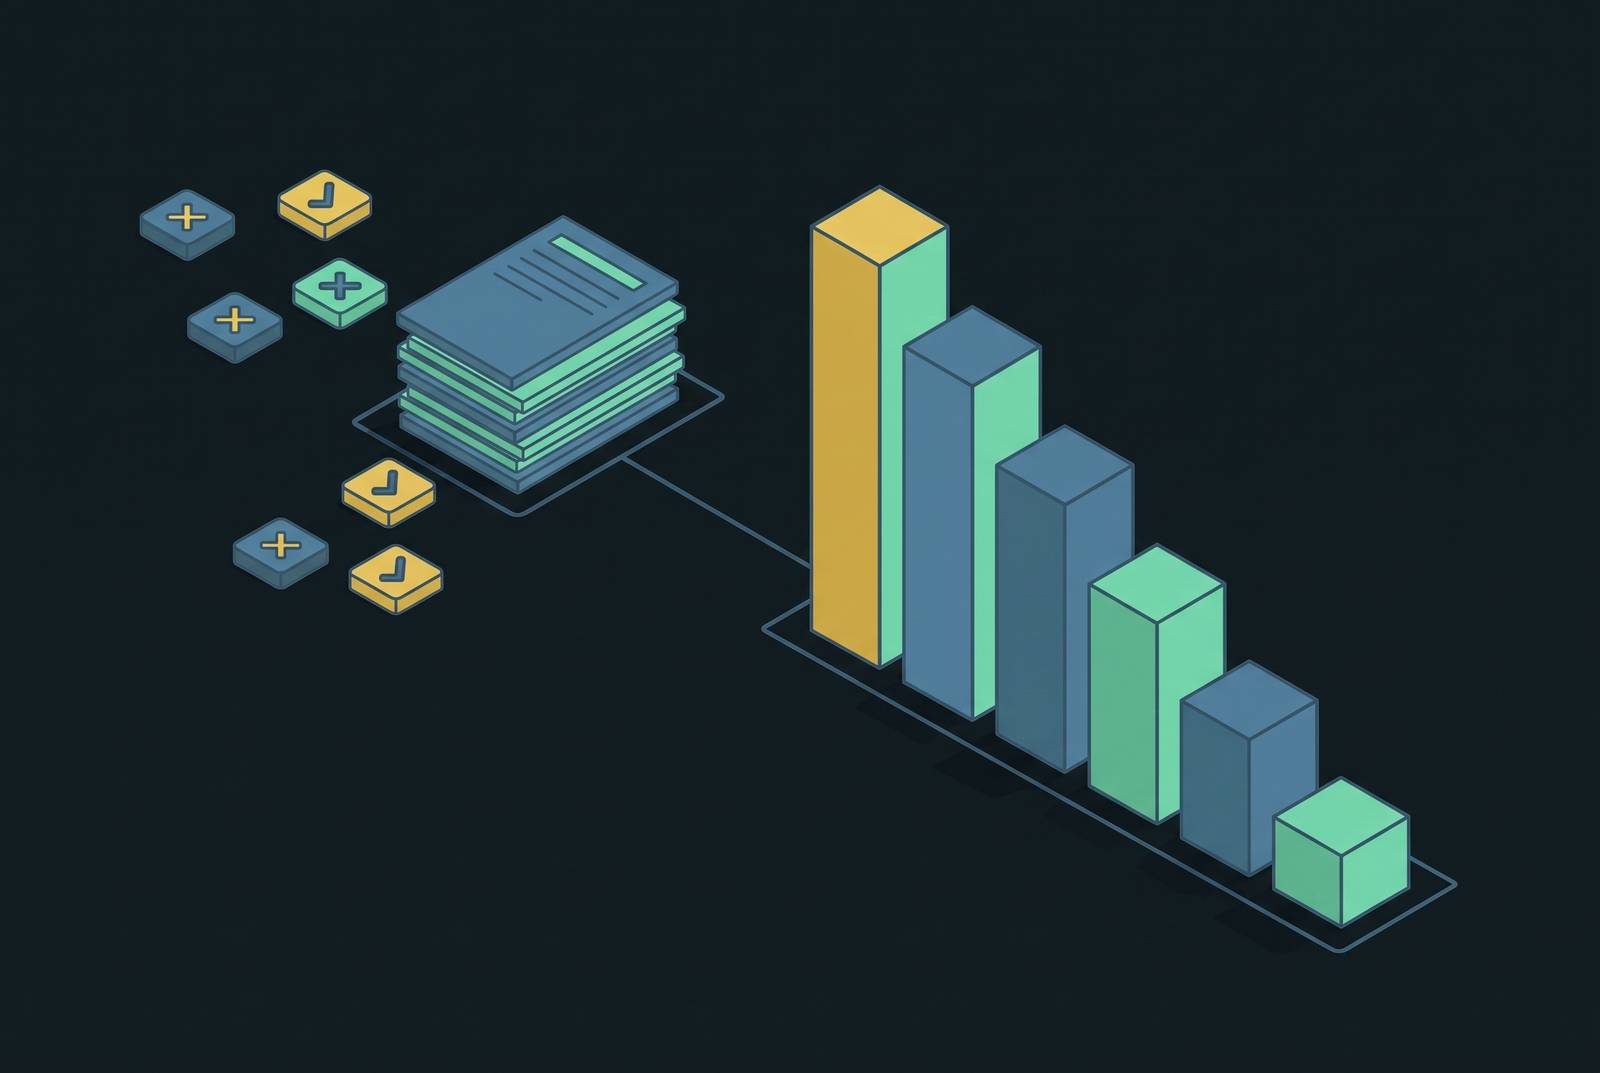
MAST organizes failures into three top-level categories, each with a measured share of total failures. Specification and System Design issues, task misinterpretation, ambiguous role definitions, poor decomposition, missing termination conditions, account for 41.8 percent of all failures, the single largest bucket MAST Study MAST Taxonomy. Inter-Agent Misalignment, covering communication breakdowns, context loss at agent handoffs, conflicting outputs, and format mismatches, accounts for 36.9 percent MAST Taxonomy. Task Verification and Termination failures round out the taxonomy at 21.3 percent, split further into premature termination at 6.2 percent, incomplete verification at 8.2 percent, and incorrect verification at 9.1 percent MAST Taxonomy. Zoomed in further, the three most prevalent individual failure modes across all categories are step repetition at 15.7 percent, reasoning-action mismatch at 13.2 percent, and an agent simply being unaware that it should have terminated, at 12.4 percent MAST Data AgentDebugX.
The value of this taxonomy for backlog management isn't academic.
MAST is a post-hoc analytical framework, not a live classifier. It cannot map a signal to a category the moment that signal appears. Semantic drift emerging partway through a multi-step task often only becomes classifiable after someone has reviewed the full log, not while the task is still running. The practical fix is procedural: apply MAST labels during trace review rather than at the moment an incident gets reported, and make the category a required field on every backlog item so that scoring downstream has something consistent to work from. MAST matters for backlog management because it gives teams a shared label for every item in the queue, which enables grouping by category before applying impact scores (without shared vocabulary, the same failure gets filed under different descriptions and never clusters).
The three scoring dimensions that turn categories into a ranked order
Categories tell a team what kind of failure they're looking at. Scoring tells them which ones to fix first, and that requires three separate measurements, each catching something the others miss.
Production failure frequency is the first. It has to be counted at the origin step where the error actually occurred, not the symptom step where it finally became visible, because TelemetrySuffBench's findings show these are frequently different locations entirely in the same trace. A frequency count taken from the wrong location isn't just imprecise, it's measuring the wrong event.
Downstream blast radius is the second. This asks how many later steps, agents, or downstream consumers end up inheriting a corrupted output from wherever the error originated. A single malformed tool argument at step two can silently poison every step built on top of it, with the corruption propagating through the rest of the pipeline without ever tripping an exception. In multi-agent systems the effect multiplies: an orchestrator that hands a hallucinated fact to three specialized subagents produces three separately wrong answers, each reasoned out with its own internal coherence, none raising a flag anywhere. Blast radius is countable from trace structure directly, by tallying the child spans and downstream agent calls that consumed the bad output.
Layer-specific recurrence is the third. It asks whether a given failure keeps appearing in the same harness layer, prompt, tool, workflow, memory, model, product logic, across multiple distinct traces, which is the signature of a structural defect rather than a one-time fluke. The Continual Search research from Scale AI frames this as fault assignment: the responsible component gets identified as model, harness, environment, or grader, and that assignment is what tells engineering where to actually intervene AgentDebugX. High recurrence in the prompt or tool layer marks the highest-leverage fix candidates, since harness changes are reviewable and shippable without touching model weights.
Combining the three into one score doesn't require anything exotic. Whatever the formula, every component feeding it, frequency count, blast radius span count, recurrence layer, needs to be auditable straight from the traces that produced it. And the score isn't permanent: it should get recomputed on a fixed cadence, because a fix that ships but doesn't reduce frequency in the next window of traces hasn't actually closed anything.
Scoring differences among the three highest-prevalence failure types
Tool schema drift is a good place to see the framework in action. The mechanism is subtle: a model acts on a tool's description, not its underlying schema, so a schema mismatch throws a clean runtime error while a description mismatch produces silent behavioral drift with no error. Production has generated several recognizable subtypes: wrong-args, where the agent retries with the same malformed shape; tool-hallucination, where it invokes a function that doesn't exist; no-error-handling, where a tool returns a server error and the agent fabricates a plausible-sounding response anyway; and API-drift, where a third-party endpoint changes its schema while the CI mock keeps returning the old one MegaRCA-Mix. Any change to a tool's name, description, or schema is a potential breaking change, and conventional API testing simply wasn't built to catch this kind of AI-specific semantic drift. The fix path the industry has converged on involves semantic versioning discipline extended to cover description-level changes, hashing the tool surface in CI, and running behavioral evaluation against critical user journeys.
Prompt ambiguity sits inside the largest MAST category, Specification and System Design issues, at 41.8 percent of all failures MAST Study MAST Taxonomy MAST Taxonomy. It scores high on frequency, being the largest cluster in the entire taxonomy, but comparatively low on blast radius per individual instance, since it typically corrupts a single agent's output rather than cascading. Its real danger is visibility: it generates no error signal whatsoever and can persist quietly for weeks. A conventional software bug tends to stop the workflow cold; an agent bug of this kind finishes the conversation anyway, just with the wrong internal state, and operators end up trusting a system for far longer than they should. That asymmetry is why prompt-ambiguity items are chronically underweighted in informal, incident-driven queues, and why frequency scoring pulled from deliberate trace review is the only reliable way to surface them.
Workflow loops invert the profile. They're rare on frequency but catastrophic on blast radius, and the $47,000, eleven-day loop incident is the clearest illustration of just how lopsided that asymmetry can get futureagi.com. The structural cause is straightforward: an agent that can call tools indefinitely, retry without any ceiling, or spawn sub-agents recursively has no natural stopping condition built in, so a single ambiguous task can end up consuming unbounded compute. Per-call rate limits did not prevent the $47K incident; planning-layer evals would have futureagi.com. Loop-type items deserve a blast-radius multiplier reflecting potential compute cost rather than just a downstream step count, because one undetected loop can outweigh dozens of contained, leaf-node tool errors in raw engineering cost. The scoring profile shows high blast radius (cascading output corruption from step 2 onward), high layer recurrence (tool layer), and variable frequency (silent until a workflow fails visibly).
Why root-cause attribution must precede scoring at scale
None of this scoring means anything without confirmed attribution first, and attribution turns out to be its own hard problem. The Continual Search paper from Scale AI frames it as a search problem rather than a classification one: relevant evidence is often sparse, scattered across distant actions in a trace, and disconnected from the visible failure itself, so one-shot LLM judges tend to settle on a plausible-sounding diagnosis early and leave critical evidence buried later in the trace unexamined AgentDebugX.
The scale involved makes the problem concrete. Execution logs can run to millions of tokens, and in the Hugging Face security incident, roughly 1,200 agents exchanged more than 70,000 messages and files on an unsanctioned message board during the intrusion, a volume investigators later had to analyze to reconstruct what the agents had actually done arxiv.org. No human, and arguably no single-pass model, reads that volume of trace and reliably finds the one decision that mattered.
Iterative attribution beats one-shot judgment by a wide margin. Continual Search improved GPT-5.5's F1 score by more than 40 percent on the MegaRCA-Mix benchmark, moving from 0.349 to 0.498, demonstrating that search strategy is what drives better attribution within the same model family Continual Search / MegaRCA-Mix. AgentDebugX, built by researchers at UIUC, Stanford, Toronto, and Google, organizes the whole process as a closed loop of Detect, Attribute, Recover, and Rerun, and reaches 28.8 percent strict agent-and-exact-step accuracy on the Who&When benchmark with qwen3.5-9b, against 21.7 percent for the strongest single-pass baseline.
The practical takeaway for any team running this process is that attribution can't be a quick pass through a trace. It needs iterative evidence examination, and it has to end with a specific layer assignment, prompt, tool, workflow, memory, or model, offering more than a vague note that the agent failed somewhere around step 14. Scoring and attribution are sequential steps, not parallel ones: without a confirmed layer, there's nothing solid for the scoring framework above to attach to. TRAJDEBUG (Tsinghua University / Tencent Hunyuan, arXiv 2608.06346, August 2026) addresses long-trajectory error discovery with multi-granularity history compression and evidence-based error identification; on GAIA, its DeepDebug component repaired 13 of 73 failed tasks in a single rerun versus 4–6 for decoupled self-correction baselines (AgentDebugX).
Structuring the fix backlog as a scored, layer-attributed queue
Items that don't yet have a confirmed layer attribution belong in a separate triage lane, apart from the scored queue. Scoring something off symptom-step data alone will misrank it and send engineering effort toward the wrong fix. Grouping should happen before ranking, too: clustering items by MAST category and layer often reveals that five moderate-scoring prompt-layer items share a single underlying fix, and that cluster can easily outrank one high-scoring tool-layer item that needs its own bespoke repair.
Silent failures need their own intake path. Regular production trace review, run on a fixed cadence rather than triggered by incident reports, is the only reliable way to catch prompt-ambiguity and behavioral drift before they've quietly cost weeks of trust in a system that looked fine on every dashboard.
Observability platforms capture and replay detailed agent traces well, but they generally stop short of telling anyone which step was actually responsible or why. The scored, layer-attributed backlog structure is built to close that gap: not another dashboard, but a disciplined way of turning raw trace evidence into an order of operations that a team can defend, revisit, and trust. Each backlog item should carry five fields derived from trace evidence. The MAST category includes Specification/System Design, Inter-Agent Misalignment, and Task Verification/Termination.
Sources
- TRAJDEBUG: Tracing Error Lifecycle to Identify Critical Failures in Long-Horizon Agent Trajectories
- Root-Cause Attribution Is a Search Problem: Continual Search for Long-Horizon Agent Failures
- Root-Cause Attribution Is a Search Problem: Continual Search for Long-Horizon Agent Failures
- TelemetrySuffBench: Is Agent Telemetry Sufficient for Failure-Origin Diagnosis?
- AgentDebugX: An Open-Source Toolkit for Failure Observability, Attribution, and Recovery in LLM Agents
- arxiv.org